The AI Data Licensing Market Map: Who's Buying, Licensing, and Supplying Enterprise Data in 2026?
Explore companies buying, licensing, and supplying data for AI in 2026. Discover enterprise data buyers, marketplaces, and licensing opportunities.
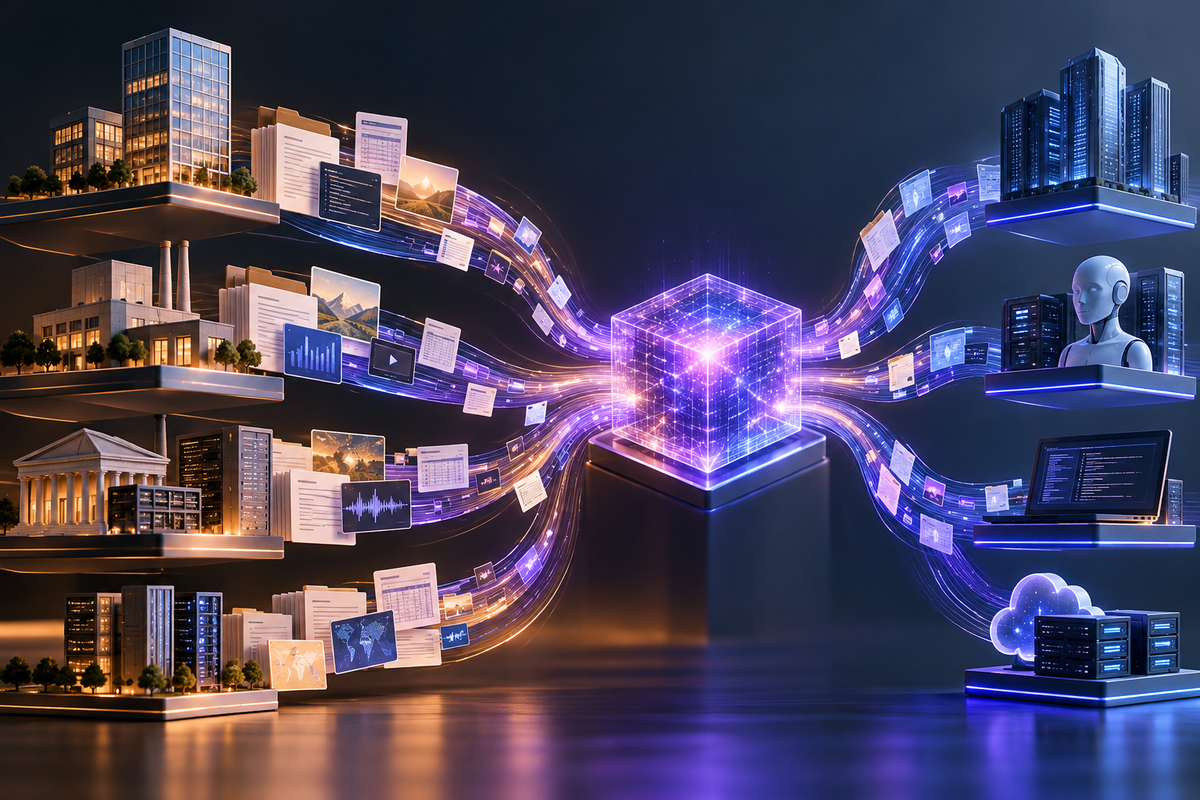
For years, companies have accumulated vast libraries of operational data without giving much thought to their commercial value.
Customer support tickets, engineering workflows, financial models, laboratory records, project histories, and internal knowledge bases were created to help businesses operate. Now, a growing industry is emerging around licensing that information to artificial intelligence developers.
The economics are beginning to attract serious attention.
In October 2026, AI data company micro1 announced a commitment to spend $1 billion over 12 months acquiring and licensing enterprise operational data. Handshake AI has launched a program to purchase business records for training and evaluation, while companies including Troveo, Mercor, and Nyne are actively marketing data licensing opportunities to business owners.
An entirely new question is entering the corporate conversation: Could the information our business produces every day be valuable to someone building AI?
The answer depends on what the company owns, how that information was collected, and whether a buyer needs it. But the emergence of dedicated acquisition programs suggests that enterprise data is becoming a distinct commercial market.
In this post we examine 19 companies helping that market take shape, from direct data buyers and licensing intermediaries to content marketplaces and AI training infrastructure providers.
The AI Data Licensing Market Map
Four segments of the AI data economy
Companies grouped by their primary role. Some participate in more than one segment.
Enterprise Data Acquisition
Companies licensing operational records and business workflows.
Marketplaces & Intermediaries
Connecting rights holders and data buyers.
Content & Media Licensing
Licensing text, images, video, and creative work.
Data Production & Infrastructure
Creating, curating, and evaluating AI training datasets.
Editorial classification, not a ranking of purchasing volume or confirmation of active data-buying mandates.
1. Enterprise Data Acquisition
This is the segment most directly relevant to businesses considering licensing historical operational records.
These companies operate programs that acquire, license, or commercially arrange access to company data for AI development.
Mercor
Focus: Enterprise workflows, workplace documents, and operational data.
Mercor has expanded into enterprise data licensing through a program that invites companies to monetize the information generated by everyday operations.
Its public offering describes connecting workplace systems including Slack, Microsoft Teams, Gmail, Salesforce, GitHub, and Notion, then processing and de-identifying selected data for licensing.
This model is especially relevant to businesses with long histories of digital collaboration and documented technical work.
Enterprise Workflow Data for Frontier AI
micro1
Focus: Operational workflows, business documentation, and reinforcement learning environments.
micro1 is one of the clearest signals of how the enterprise data market is developing.
On October 9, 2026, the company announced its $1 billion enterprise data acquisition commitment. Its stated objective is to use de-identified operational records to construct training environments that reflect how businesses actually function.
The company identifies software engineering, finance, recruiting, customer support, and other organizational workflows as relevant categories.
Its published partnership criteria prioritize operationally mature companies with at least 30 employees and established documentation.
Handshake AI
Focus: Real business workflows and operational data.
Handshake AI has introduced a program that connects company records with frontier model developers.
Its published eligibility guidelines specify businesses with at least 20 full-time employees and three or more years in operation.
The company says its process involves scoping, de-identification, and confidential delivery of data for AI training and evaluation.
Handshake advertises qualified partnership values ranging from $100,000 to $4 million. Those figures are company-stated possibilities rather than independently verified typical payouts.
Nyne
Focus: Accounting, CRM, service histories, and business operations.
Nyne markets a program for licensing historical business records to AI developers.
The company highlights records from accounting systems, customer relationship management software, scheduling platforms, and project management tools.
Its proposition reflects a broader shift toward datasets containing the decisions and interactions behind completed work, including how a customer issue was resolved or an operational process evolved.
Nyne says participating businesses retain control over the scope of information shared and receive compensation under a negotiated agreement.
Prism by Labelbox
Focus: Enterprise operational systems, expert work, and workflow records.
Prism offers a dedicated commercial pathway for businesses interested in licensing records generated by their existing systems.
Its platform references Salesforce, Jira, ServiceNow, SAP, Slack, and other enterprise tools. Published categories include financial reasoning, expert decision-making, business processes, and operational histories.
Prism's website describes licensing structures involving upfront payments and potential revenue sharing. It also states that some arrangements are exclusive by default, making contractual terms particularly important for prospective data owners.
Polyshares
Focus: Historical operating records across industries.
Polyshares describes itself as a direct licensing counterparty rather than a traditional marketplace.
Its published model involves reviewing a company's operational record, negotiating a defined license, and paying the business directly before supplying licensed data to AI customers.
The company identifies email, CRM histories, support tickets, project records, accounting systems, and internal documents as potentially relevant.
Polyshares advertises typical agreements between $100,000 and $2 million, though actual transaction values and availability require independent verification.
Grepped
Focus: Company records, existing datasets, and reinforcement learning environments.
Grepped operates a sourcing intake for multiple forms of AI training material, including internal business records, standalone datasets, and reinforcement learning environments.
Its process allows data owners to describe what they have before a potential transaction is evaluated.
For businesses with proprietary technical or operational information, Grepped represents a route to assessing possible licensing demand without initially preparing a complete dataset.
2. Data Marketplaces & Licensing Intermediaries
Not every data owner has an existing relationship with an AI laboratory. Intermediaries help bridge that gap.
They may identify potential buyers, package datasets, negotiate licensing terms, support compliance, or facilitate commercial introductions.
Troveo
Focus: Business records, video, audio, gaming, and other real-world datasets.
Troveo combines data sourcing with a marketplace-style licensing model.
Its business offering explicitly targets companies with historical email, support tickets, CRM data, documents, and operational records.
Troveo states that companies can receive a share of revenue from multiple licensing transactions involving the same underlying data, rather than relying solely on a single sale.
The company also supplies specialized video, audio, and gaming datasets to AI developers.
Protege
Focus: Healthcare, video, audio, spatial, and specialist datasets.
Protege connects data providers with organizations developing AI models.
Its platform focuses on sourcing private and proprietary data across specialized domains, with an emphasis on rights protections and preparing datasets for model development.
Unlike broad enterprise workflow programs, Protege's public materials identify particular opportunities involving healthcare, spatial information, audio, video, and emerging modalities.
The company operates a dedicated data-provider intake process.
Pewter
Focus: Historical business records and licensing transactions.
Pewter works with business owners to assess whether their company records may be suitable for licensing to AI developers.
Its process covers valuation discussions, negotiation, coordinating exports, de-identification, and delivery through licensing partners.
The firm emphasizes established U.S. businesses, particularly those with 20 or more employees and at least three years of historical records.
Pewter identifies logistics, accounting, engineering, construction, manufacturing, and professional services among its areas of interest.
Datarade
Focus: Commercial datasets across industries.
Datarade operates a business-to-business data marketplace where providers can publish datasets and connect with prospective buyers.
Its marketplace spans financial data, alternative data, geospatial information, consumer insights, and AI training datasets.
Datarade's role differs from that of companies acquiring internal business workflow histories. It is particularly relevant to organizations that already have a clearly defined dataset they can legally commercialize.
SimpleClosure
Focus: Source code, software projects, and digital assets.
SimpleClosure approaches the data licensing opportunity through startup asset disposition.
Its AssetHub connects companies, including those winding down, with buyers interested in source code, repositories, documentation, and certain forms of historical workspace data.
In a September 2026 research update, SimpleClosure reported that more than 350 companies had offered assets through its marketplace, representing nearly 500 million lines of code.
Its work raises an interesting possibility: valuable AI training material may remain inside companies long after the underlying product or business has ceased operations.
3. Content & Media Licensing
A parallel market is developing around creative works and professionally produced content.
AI developers need rights-cleared images, video, audio, and text. Publishers and creators, meanwhile, are seeking more control over how their work is used and how they are compensated.
Shutterstock
Focus: Images, videos, audio, 3D assets, and multimodal training datasets.
Shutterstock has expanded its data licensing business to supply content for AI model development.
In March 2026, the company announced an expansion of its licensed training datasets, emphasizing multimodal content for model training and refinement.
Its licensing offering includes rights-cleared content and customized dataset sourcing for AI developers.
Shutterstock illustrates how an established commercial content library can become a supplier to the AI industry.
Wirestock
Focus: Creative images, videos, designs, music, and custom multimodal datasets.
Wirestock works with creators to license their content and produce datasets tailored to AI developers.
Its model combines an existing contributor network with custom content production.
The company reports more than 700,000 creators in its network and over 10 million assets licensed for AI, although those figures are self-reported.
Wirestock demonstrates how creative communities can collectively supply commercially valuable training material.
Created by Humans
Focus: Books, written works, and author-controlled AI licensing rights.
Created by Humans provides infrastructure for authors and rights holders to manage the use of their writing by AI companies.
Its platform lets participating authors opt into different categories of AI licensing, manage permissions, and receive compensation for approved use.
The company is an example of how the data licensing market extends beyond databases and enterprise records into intellectual property and negotiated content rights.
4. Data Production & Infrastructure
These companies help turn raw information, expert knowledge, and other inputs into usable training and evaluation data.
They are important participants in the ecosystem, although their business models should not be confused with direct purchasing programs for a company's historical operating records.
Scale AI
Focus: Human feedback, expert annotation, evaluations, and model training data.
Scale AI provides infrastructure and services for improving AI models using high-quality data and human evaluation.
Its Data Engine supports reinforcement learning from human feedback, data generation, safety testing, and evaluations.
Scale is a major example of the companies providing the data production layer that sits between model developers and the information needed to improve model capabilities.
Appen
Focus: Specialized AI datasets, coding environments, multimodal content, and evaluation data.
Appen offers datasets and data services for developing and testing machine learning systems.
Its catalog includes coding tasks, private code repositories, language data, audio, images, and other specialized materials.
The company also markets access to real-world engineering histories, including code commits, pull requests, and testing environments.
Those categories are particularly relevant as AI developers build coding agents and systems expected to complete complex tasks across software environments.
Defined.ai
Focus: Speech, language, image, video, and specialist AI datasets.
Defined.ai operates a marketplace for datasets used in machine learning development.
Its catalog includes speech recordings, medical imagery, computer vision datasets, and multilingual resources.
The company represents the more established dataset marketplace model, where customers purchase access to curated data products suited to defined technical requirements.
Labelbox
Focus: Training data workflows, annotation, and evaluation infrastructure.
Labelbox supports the creation and management of labeled datasets for AI development.
Its broader data platform is distinct from the enterprise licensing program marketed through Prism. One helps organizations prepare and evaluate data for AI systems; the other focuses on obtaining commercially usable operational data.
Together, they illustrate how sourcing and preparing training data can occupy different layers of the same market.
Which Types of Enterprise Data Are Attracting Interest?
Across the public sourcing programs reviewed for this map, several patterns emerge.
The companies acquiring operational data repeatedly reference histories of human decision-making, technical work, and business processes rather than isolated records.
That gives us a useful framework for understanding potential demand.
Data category | Examples | Potential AI applications |
|---|---|---|
IT & technical support | Tickets, incident histories, troubleshooting notes | IT agents, support automation |
Software development | Code repositories, PRs, bug histories | Coding agents, software evaluation |
Sales & customer operations | CRM activity, proposals, support cases | Sales and customer service agents |
Finance & accounting | Workbooks, reconciliations, forecasting | Financial reasoning and workflow automation |
Manufacturing & laboratories | Test results, quality reviews, exceptions | Scientific and industrial AI |
Project management | Tasks, decisions, approvals, handoffs | Enterprise workflow agents |
Professional services | Research, document revisions, project deliverables | Specialist knowledge-work agents |
These are examples of potentially relevant data, not guarantees of purchase. Actual buyer requirements change, and some categories involve heightened legal or privacy restrictions.
Five Signals Shaping the AI Data Economy
1. Real-world business workflows are becoming training material
The strongest emerging theme is demand for examples of how work happens.
A finished customer support answer provides information. A complete support history can preserve the original issue, the investigation, the attempts that failed, the escalation, and the eventual resolution.
That sequence can be useful for developing systems capable of reasoning through multi-step tasks.
It also explains the interest in historical records from Jira, ServiceNow, GitHub, Salesforce, and other workplace platforms.
2. Data acquisition is becoming a specialized business function
Programs from micro1, Handshake AI, and others indicate that acquiring proprietary operational data increasingly requires dedicated commercial teams.
Companies must identify potential data owners, assess eligibility, negotiate agreements, resolve privacy questions, and coordinate delivery.
The market is developing a familiar enterprise-sales structure, but with datasets as the commercial asset.
3. Licensing structures are still fragmented
Some companies describe direct purchasing agreements. Others offer marketplaces, revenue-sharing arrangements, or brokerage-style services.
Compensation may depend on the dataset's quality, scarcity, permitted uses, exclusivity, and the number of downstream customers.
There is no universal pricing model.
That leaves businesses with an important responsibility: understanding what rights they are granting, for how long, and under what conditions.
4. Historical depth may matter as much as raw volume
A dataset with millions of disconnected entries may be less useful for certain AI applications than a smaller collection that preserves the full sequence of an expert completing a difficult task.
For example, a software repository with issue histories, code changes, review comments, tests, and final resolutions can contain richer information than the source code alone.
This helps explain why providers increasingly emphasize workflow completeness, metadata, and operational context.
5. A market for data intermediaries is taking shape
Most business owners do not maintain relationships with frontier AI laboratories.
Likewise, an AI lab searching for highly specialized operational records cannot easily identify every business that might own suitable information.
Intermediaries, marketplaces, and licensing advisers can reduce that discovery and transaction friction.
As the sector develops, the ability to identify legitimate rights holders, understand buyer requirements, and facilitate compliant licensing agreements may become increasingly valuable.
What Should Businesses Know Before Licensing Their Data?
For business owners, the opportunity is worth exploring carefully.
A company may have years of valuable operational knowledge stored across software systems without having a legal right to commercialize every record.
Customer contracts, employee privacy, confidential information, software-provider agreements, intellectual property rights, and data protection regulations may restrict what can be shared.
Before entering a licensing agreement, businesses should consider five questions:
- What data do we actually own or have permission to license? Holding records in a company's systems does not automatically establish unrestricted commercial rights.
- What will the buyer use the information for? Training, evaluation, fine-tuning, and other uses may require different permissions.
- How will sensitive information be protected? De-identification can reduce risk, but does not eliminate the possibility of re-identification.
- Will the agreement be exclusive? Exclusivity may prevent a company from licensing the same information to other buyers.
- When and how will the business be paid? A quoted valuation, signed contract, completed delivery, and received payment are different milestones.
Businesses should establish these details before transferring records, samples, or system access.
For Businesses: Explore Data Licensing Opportunities
FEED THE AI / DATA PARTNERSHIPS
Feed The AI / Data Partnerships
Could your company's data be valuable to AI developers?
Your business may have years of operational records that could be relevant to AI training and evaluation.
Feed The AI helps companies explore potential data licensing opportunities and identify relevant partners. No confidential documents or datasets are needed for an initial inquiry.
Explore Data LicensingSubmitting an inquiry does not guarantee eligibility, an offer, or payment.
For AI Data Companies: Get Listed
The AI Data Licensing Market Map is a living research resource.
If your company acquires, licenses, brokers, produces, or distributes proprietary data for AI development, we welcome submissions for editorial consideration.
To suggest a company, contact us with a description of its business model, data categories, and relevant public sources.
Inclusion is subject to editorial review and does not require payment.
The Market Is Still Taking Shape
AI developers have spent years competing over compute, talent, and model performance.
Another competitive frontier is emerging around access to high-quality, legally usable data.
That market now includes direct acquisition programs, specialist sourcing firms, established content licensors, and infrastructure providers preparing increasingly sophisticated datasets.
The commercial opportunity for businesses is still uncertain. Published pricing often comes from the companies offering licensing services, while actual transaction terms are frequently confidential.
But the direction is becoming clearer: operational knowledge accumulated inside businesses is attracting interest from organizations building the next generation of AI.
For the companies supplying that knowledge, the important question is no longer simply how much data they have.
It's what their data can teach.